↵Open
Schematic changelog
Inference Pricing
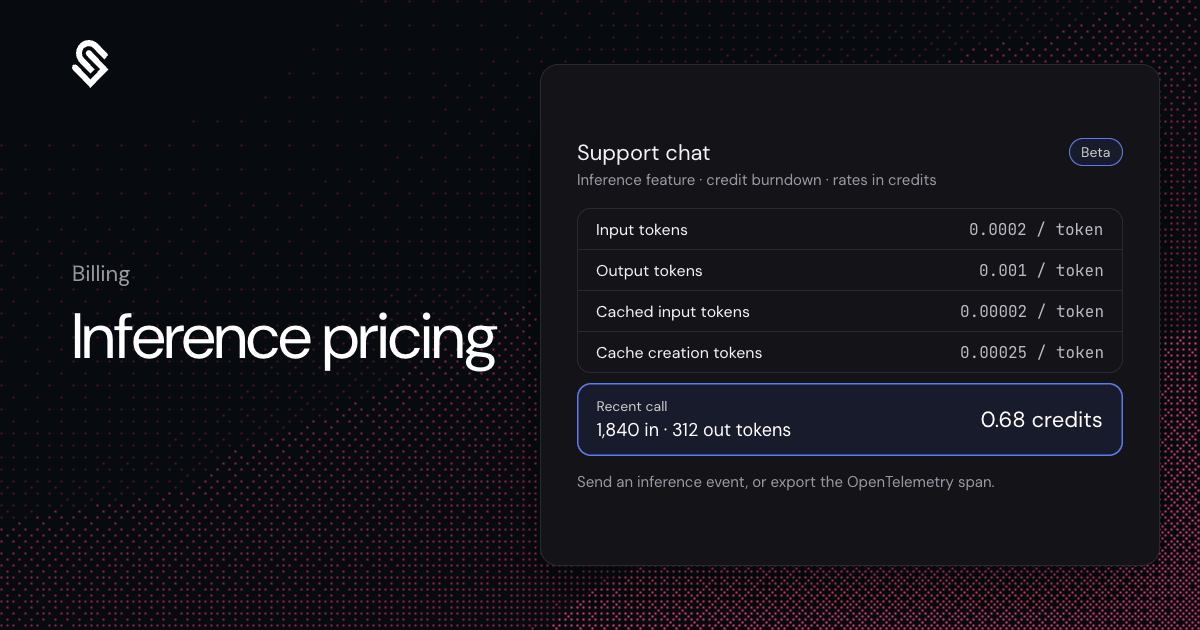
Providers price input, output, cached input and cache writes differently, so a flat rate per request charges a long prompt and a one-line question the same.
Inference pricing burns credits for every LLM call at per-token rates. Your app sends one inference event per model call with the company, the model and the provider's token counts. Or export the call's OpenTelemetry span to c.schematichq.com/v1/traces, where Schematic reads the standard gen_ai.* token attributes and you add the company and feature event name as schematic.* attributes.
An inference feature is an event-based feature whose event source is inference events. Its credit burndown entitlement has a rate per call plus rates for input, output, cached input, cache creation and reasoning tokens, all in credits. Before you publish, the form shows what a recent call would burn.
Preflight checks price a call from its token counts, so you can refuse an oversized request before it runs. Burns go through leases and reservations, and every draw is on the credit ledger.
Every inference event also records what the call cost you: the cost your app sends, or Schematic's list price for the model at the time of the call, kept for Anthropic and OpenAI models and repriced when a list price changes. The cost shows on the event and ledger entry drawers, and the company inference cost endpoint in the API and get_company_inference_cost in the MCP return a company's cost for a period by model, so you can check that your rates cover your model spend.
Docs: Inference pricing, Track what calls cost you and Inference pricing with OpenTelemetry
Beta. Ask us to turn it on.